LSI

AI Readiness Assessment: How to Know If Your Organisation Is Ready for AI Transformation

20 min read
07 Oct 2026

An AI readiness assessment helps an organisation decide whether it can apply AI to a specific use case and what needs to be in place first. It examines whether the opportunity has measurable value, the required data and technology are available, responsibilities and safeguards are clear, and the people running the workflow can respond when the system fails or produces an unsuitable result. This guide presents a seven-dimension framework, an evidence checklist and an illustrative scorecard. Use them to decide whether to reframe the opportunity, address a capability gap, run a bounded pilot or scale in stages. Readiness depends on the use case and the evidence behind each capability.

Podcast: Listen to the insight

0:00
AI readiness measures capacity for change, not enthusiasm for tools

AI readiness measures capacity for change, not enthusiasm for tools

An AI readiness assessment should reveal whether your organisation can turn a defined AI opportunity into governed, adopted and measurable change. Use this evidence-led framework, checklist and scorecard to decide whether to reframe, repair, pilot or scale.

AI readiness is an organisation’s current ability to turn a defined AI opportunity into governed, adopted and measurable operational change. It depends on strategic clarity, decision rights, data, technology, governance, workflow readiness and people’s capacity to adopt new ways of working.

Enthusiasm is easy to mistake for preparedness. Leadership may have approved funding, employees may be testing public AI tools and a supplier may have demonstrated a convincing prototype. None of these conditions proves that the organisation can use AI safely in a live process or sustain its value.

A useful assessment therefore asks for evidence. A strategy should identify the decision or workflow that needs to improve. A governance policy should assign decision rights and operate in practice. Claims about data should be tested against the requirements of the proposed use case.

Major assessment approaches also extend beyond technology. Microsoft’s assessment covers business strategy, governance and security, data, organisational culture, infrastructure and model management. Cisco examines strategy, infrastructure, data, governance, talent and culture. The labels differ, but both treat technical capacity as one part of organisational readiness. See the Microsoft AI Readiness Assessment and Cisco AI Readiness Assessment.

AI readiness and AI maturity answer different questions

Readiness asks whether the necessary conditions exist to begin or extend a particular AI initiative. Maturity asks how consistently and effectively the organisation already develops, governs and operates AI.

An organisation may be mature in one capability and unready for another use case. It might operate forecasting models reliably but lack the content rights, evaluation methods or human-review controls required for a generative AI assistant.

The reverse is also possible. A team may be ready to run a narrow, low-risk pilot without having an enterprise-wide AI operating model.

The distinction prevents an unhelpful race towards the highest maturity level. The MITRE AI Maturity Model notes that an appropriate target depends on mission requirements and available resources.

The relevant question is not whether every capability is advanced. It is whether the capabilities required by the proposed use case are sufficient and supported by credible evidence.

Organisation-wide readiness does not guarantee that a use case is ready

Enterprise assessments identify shared strengths and weaknesses. They can inform investment planning, governance design and capability development. They do not replace a use-case review.

Every use case has its own value hypothesis, data dependencies, affected people, failure modes and accountability requirements. A customer-service assistant and a workforce-planning model may use the same cloud platform while creating different risks.

Assess readiness at two levels:

  • Organisation level: Can shared capabilities support AI work repeatedly?
  • Use-case level: Can this application create value within acceptable operational and governance boundaries?

Record the level being assessed at the beginning. Otherwise, participants may answer the same question with different scopes in mind and produce a score that appears precise but cannot support a decision.

A broad score can hide the constraint that stops delivery

Readiness is constrained by dependencies.

A broad score can hide the constraint that stops delivery

Strong infrastructure cannot compensate for data that cannot lawfully be used. A clear business case cannot compensate for the absence of an accountable owner. Training activity cannot compensate for a workflow in which employees have no time or authority to use the proposed system properly.

The LSI approach therefore does not treat a high average as proof of readiness. It combines a seven-dimension profile with evidence confidence, critical gates and comparisons between respondent groups.

An assessment is not a certification, technical audit or legal opinion. It is a structured management diagnosis. Specialist security, data protection, employment, procurement and sector-specific reviews may still be required.

Advanced AI Prompt Engineering

Large language models, such as ChatGPT, have transformed how we interact with technology. Leveraging their full capabilities, however, requires more than basic queries. This module delves into the art and science of crafting prompts that elicit...

Learn more

AI Readiness Assessment Framework

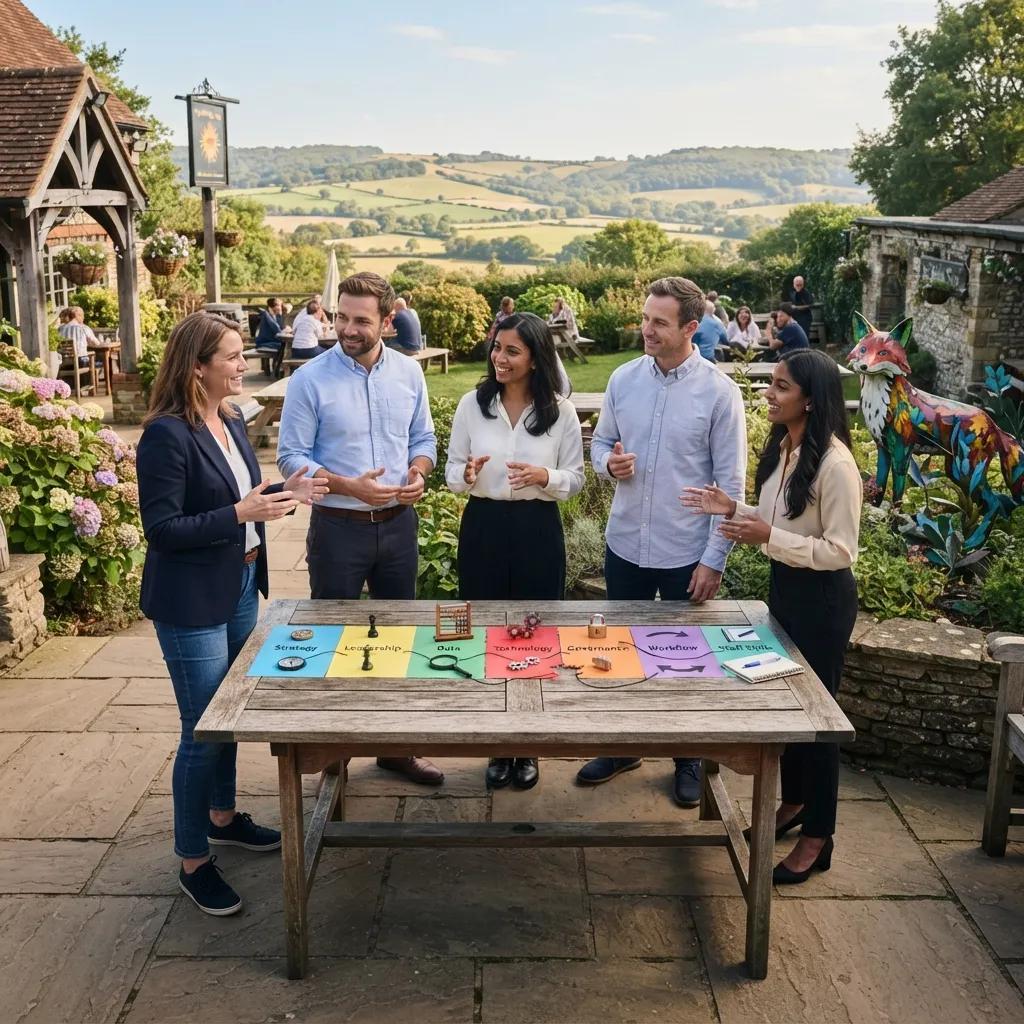
This framework uses seven dimensions. They are separated to expose gaps but should be interpreted as an interconnected system. A data problem may originate in unclear ownership, while resistance to adoption may reflect a poorly designed workflow rather than a cultural objection.
AI Readiness Assessment Framework

Strategic value and use-case clarity

Readiness begins with a decision or workflow worth improving, not with a technology looking for somewhere to be used.

Define the user, current problem, intended outcome and baseline performance. Explain why AI is more appropriate than a simpler process or software change.

The use case should have a testable value hypothesis, measures of success and explicit stop conditions. Otherwise, a pilot may appear successful because the team measures technical activity while overlooking cost, disruption or harm.

The MSc Digital Innovation and Entrepreneurship curriculum examines how AI opportunities can be shaped around real user needs, value propositions and commercially credible business cases.

Leadership, decision rights and funding

Executive sponsorship matters, but sponsorship alone is not ownership.

A ready initiative has someone accountable for the business outcome, named owners for delivery and risk decisions, and a funding path extending beyond a demonstration.

Decision rights should cover who can approve a pilot, accept residual risk, change the workflow, pause deployment and authorise expansion.

Data and knowledge foundations

Assess the information required by the use case rather than the organisation’s total volume of data.

Relevant considerations include availability, quality, representativeness, lineage, access controls, retention rules and permission to use the information for its intended purpose. For knowledge-based systems, examine document ownership, currency and conflicting sources.

The question is not whether the organisation has a data warehouse or a large document collection. It is whether the required information can be accessed, understood and maintained at the quality the application needs.

Where this is the central constraint, LSI’s GenAI data infrastructure readiness guide provides a more focused next step.

Technology and integration capacity

Technology readiness concerns the path from a controlled test into the systems where work happens.

Review architecture, identity and access management, integration interfaces, testing environments, observability, resilience and supplier dependencies.

A small internal pilot does not require the operating environment of an enterprise-wide service. It does, however, need a credible route to deployment if the evidence supports proceeding. Otherwise, it tests a model in isolation while leaving the difficult integration questions unanswered.

Governance, security and accountability

Governance should connect principles to decisions.

Identify applicable obligations, likely harms, affected groups, review points and the person authorised to accept or reject risk. Define how decisions and system changes will be recorded.

The NIST AI Risk Management Framework is voluntary and use-case agnostic. It can help structure risk-management work without assuming one sector or application.

ISO/IEC 42001 uses a management-system approach to establishing, implementing, maintaining and improving how an organisation manages AI. Neither source removes the need to interpret legal and sector-specific obligations for the proposed deployment.

Useful evidence may include risk classifications, impact assessments, threat modelling, approval records, incident routes and mechanisms for challenging or correcting outcomes. LSI’s article on accountability in AI adoption examines organisational ownership in greater depth.

Operating model and workflow readiness

AI creates value when it changes a real workflow.

Map the current process and the proposed one, including hand-offs, exceptions, human judgement and downstream consequences. Determine what happens when the system is uncertain, unavailable or wrong.

Operational readiness also includes support after launch. Someone must manage changes, respond to incidents, monitor performance and decide when reconfiguration, retraining or withdrawal is necessary.

A prototype without these responsibilities demonstrates technical feasibility, not operational readiness.

Skills, culture and adoption capacity

Assess the capabilities required by each group rather than looking only for technical specialists.

Leaders need sufficient understanding to make investment and risk decisions. Domain experts must be able to shape requirements and evaluate outputs. Affected employees need role-specific guidance, opportunities to practise and a credible explanation of how their work will change.

Culture is best assessed through behaviour. Examine whether people raise concerns, test assumptions, share lessons and stop weak initiatives. Survey sentiment can be useful, but it should be compared with participation and observed practice.

When leadership capability is the primary gap, see LSI’s guide to AI training for leadership teams.

AI Readiness Assessment Framework Examples

Frameworks serve different decisions. An organisation should not select one simply because it produces a convenient score.

Framework or approach Best suited to Contribution Boundary to recognise
Microsoft AI Readiness Assessment Guided enterprise self-assessment Broad coverage and personalised recommendations across seven pillars Responses require verification against internal evidence
Cisco AI Readiness Assessment Benchmark-oriented enterprise review Six-pillar assessment and readiness-level comparison A benchmark does not decide whether one use case should proceed
MITRE AI Maturity Model Organisational capability development Detailed dimensions and progressive capability levels It assesses maturity and is not a universal readiness target
NIST AI RMF and GenAI Profile Risk-management design Voluntary guidance supporting responsible AI risk work It is not an overall business-readiness score
ISO/IEC 42001 AI management systems Requirements for a repeatable organisational management system Management-system conformance has a different scope from use-case diagnosis
DCO AI-REAL Toolkit National and ecosystem assessment Policy-oriented assessment using pillars, dimensions and indicators Its national scope cannot be transferred directly to an enterprise

The Digital Cooperation Organization describes AI-REAL as a national assessment containing five pillars, 17 dimensions and 39 indicators. National, enterprise, workforce and use-case assessments may share themes, but their evidence and recommendations are not interchangeable. See the DCO announcement.

What company AI transformations reveal about readiness

Company cases cannot prove that one readiness framework works universally. They can show what organisational readiness looks like once AI moves beyond experimentation.

What company AI transformations reveal about readiness
Company What changed Readiness evidence Important lesson
DBS Industrialised AI across banking operations before expanding into generative and agentic AI Long-term investment in data architecture, governance, talent and operating-model change Scale followed years of organisational capability building
IKEA Retail, operated by Ingka Group Used AI for routine customer enquiries while reskilling employees for more complex work Workflow redesign, reskilling and operational measurement developed together Automation readiness includes redesigning work
Klarna Rapidly expanded AI-supported customer service and initially prioritised efficiency High usage, shorter resolution times and reported cost savings Efficiency metrics can conceal service-quality and customer-experience problems

DBS built readiness before generative AI arrived. The bank reports that it began industrialising AI in 2014. By 2025, it had more than 430 use cases supported by over 2,000 models and attributed approximately SGD 1 billion in economic value to its data analytics and AI initiatives.

More important for an assessment is what sat behind those figures. DBS identifies data architecture, responsible AI, talent and organisational agility as foundations for expansion. Its reporting also describes governance guardrails, reusable components and operating-model transformations.

The lesson is not that another organisation should reproduce its number of models. It is that access to a powerful model is not equivalent to possessing the organisational system required to use AI repeatedly. The outcomes remain company-reported rather than independent causal evidence. See the DBS 2025 CIO Fstatement and its response to shareholder questions.

IKEA Retail combined automation with role redesign. Ingka Group reported that its AI-supported chatbot, Billie, resolved approximately 47% of the enquiries it received between 2021 and 2023. This covered 3.2 million interactions and generated nearly EUR 13 million in reported savings.

Ingka also reported reskilling 8,500 customer-support employees in remote interior design, digital retail sales, relationship building and complex problem-solving.

The readiness evidence is therefore not only the chatbot’s resolution rate. It includes a redesigned division of labour and investment in the capabilities required for the work retained by people. These results are company-reported and do not constitute an independent evaluation of service quality. See Ingka Group’s account of Billie and remote selling.

Klarna shows why readiness must be reassessed. The company reported extensive adoption of its AI customer-service assistant and approximately USD 39 million in cost savings during 2024. It also estimated that the system performed work equivalent to hundreds of full-time agents.

Klarna subsequently acknowledged that it had overemphasised cost reduction and began correcting its approach towards service quality, product improvement and a continued role for people in complex interactions.

This does not mean the implementation failed. It demonstrates that technical adoption and efficiency can coexist with weaknesses in the outcome being optimised. An assessment limited to conversation volume or resolution speed might classify the initiative as fully ready. An assessment incorporating customer outcomes, exception handling and human escalation would produce a more useful diagnosis.

Klarna’s figures are company-reported in its regulatory filing. Its later strategic correction was covered by Reuters.

Across the cases, readiness becomes visible when outcomes connect to real workflows, employees are prepared for changed roles, governance works alongside delivery and operational evidence can change the original strategy.

MSc AI for Business Transformation

Artificial intelligence is revolutionising the way businesses operate, creating new opportunities and challenges; This programme is designed to equip you with the expertise to navigate this evolving landscape with confidence and precision. You will...

Learn more

Run the assessment as a cross-functional investigation

The quality of an assessment depends on who participates, what evidence they examine and how disagreements are handled.

AI Readiness Assesment
Stage What to do Output
1. Set the decision boundary State the scope, AI ambition and decision the assessment must inform Written scope and decision statement
2. Select independent assessors Include leadership, technical delivery, governance specialists and affected operations Named assessment group
3. Gather operational evidence Collect artefacts before scoring rather than relying on recollection Evidence register with owners and dates
4. Score independently Ask each group to score the seven dimensions and record its reasoning Separate score profiles
5. Investigate disagreements Identify missing evidence, different assumptions or conflicting scopes Disagreement log
6. Apply critical gates Test the conditions that must exist before piloting or scaling Gate status and accountable owner
7. Convert findings into decisions Choose reframe, repair, pilot or scale Decision record and action plan
8. Set a reassessment trigger Use a date and events such as supplier or data changes Reassessment schedule

Do not let the most senior participant determine the initial group score.

Independent scoring exposes differences that a consensus workshop may conceal. Leaders may believe data is accessible while delivery teams know permissions remain unresolved. Governance colleagues may assume human review exists while operational staff know that workload makes it impractical.

These disagreements are findings, not inconveniences to be averaged away.

Use this checklist to test the evidence behind each score

Answer every question with a link to evidence, a named owner and the date the evidence was last verified.

Use this checklist to test the evidence behind each score

Dimension Evidence questions
Strategic value and use-case clarity Is the workflow clearly defined? Is baseline performance known? Has AI been compared with simpler options? Are success and stop conditions agreed?
Leadership, decision rights and funding Is there an accountable business owner? Are approval and escalation rights explicit? Is funding available beyond experimentation? Have operational owners committed time?
Data and knowledge foundations Can the required information be lawfully accessed? Has quality been tested for the intended use? Are lineage and ownership documented? Is current knowledge maintained?
Technology and integration capacity Can the application connect securely to required systems? Is there an appropriate test environment? Are reliability and monitoring requirements defined? Are supplier dependencies understood?
Governance, security and accountability Has the use case been risk-classified? Have affected groups and potential harms been considered? Are security and privacy controls tested? Can outcomes be investigated and corrected?
Operating model and workflow readiness Is the future workflow documented? Are human review and exception routes workable? Is post-launch ownership assigned? Are outcome measures embedded in operations?
Skills, culture and adoption capacity Are capabilities mapped by role? Can domain experts evaluate outputs? Do employees have time and support to change practice? Can concerns alter the decision?

A yes or no response is not sufficient. Record whether the evidence applies across the organisation, to one business unit or only to a controlled pilot.

The checklist is a diagnostic prompt rather than a universal control set. Add sector-specific requirements and questions concerning the people affected by the system.

London School of Innovation

LSI is a UK higher education institution, offering master's degrees, executive and professional courses in AI, business, technology, and entrepreneurship.

Our focus is forging AI-native leaders.

Learn more

The LSI scorecard turns seven dimension scores into four decisions

The LSI scorecard is an editorial decision framework created for this guide. It has not been validated as a predictive instrument.

The LSI scorecard turns seven dimension scores into four decisions

Its purpose is to improve management decisions by making evidence, constraints and decision conditions explicit.

Score current evidence from absent to scalable

Score each dimension from 0 to 4. Record the rationale and supporting evidence next to the number.

Score Level Test
0 Absent The capability is missing, unknown or unsupported by evidence
1 Emerging Relevant activity exists but is informal, isolated or dependent on individuals
2 Defined Responsibilities and methods are documented, with limited evidence from practice
3 Operational The capability works in relevant operations and has repeatable evidence
4 Scalable The capability works across the required scope and can support responsible expansion

Do not award a higher score because a policy, platform or recruitment programme is planned.

Add an evidence-confidence rating to every dimension:

Confidence Evidence basis
Low Opinion, intention, anecdote or undated material
Medium Current documentation or limited pilot evidence
High Measured, repeatable operational evidence with a named owner

A score of 3 with low confidence should trigger verification rather than confidence. Keep the seven scores visible as a profile. If stakeholders request an average, show it only as a summary and never use it to override a weak critical dimension.

Critical gates cap the overall result

Before recommending a pilot or expansion, test five gates:

  1. The use case and measurable value hypothesis are defined.
  2. The required information can be used lawfully and at sufficient quality.
  3. A named owner is accountable for the operational outcome.
  4. Governance and security boundaries are proportionate to the use case.
  5. There is a viable path for human oversight, correction and stopping the system.

If a gate is not met, the decision cannot be scale.

If the missing condition would make even a controlled trial unsafe, unlawful or operationally misleading, the decision should be repair or reframe.

Cross-functional disagreement is a readiness finding

Compare the scores from each respondent group before discussing consensus.

A difference of two or more points deserves investigation. A substantial difference in evidence confidence also matters, even when the numeric score is the same.

Ask which evidence each group used, whether they assessed the same scope and whose work would absorb the risk. Do not automatically average the responses.

Agreement produced by hierarchy is not the same as shared operational understanding.

Four decisions: reframe, repair, pilot or scale

Apply the decisions in order.

Decision Assessment rule Required next move
Reframe Strategic value or use-case clarity scores 0 or 1, or AI has not been justified against a simpler option Redefine the problem, compare alternatives and narrow or abandon the proposed use case
Repair The opportunity is potentially valuable, but a gate fails, a critical dimension scores 0 or 1, or essential evidence has low confidence Resolve the named blocker and specify the evidence required before reassessment
Pilot All gates are met, every dimension required for the bounded test scores at least 2, and owners, measures and stop conditions are defined Run a controlled, time-limited test and collect operational evidence
Scale All gates are met, all seven dimensions score at least 3, critical evidence has medium or high confidence, and a pilot has demonstrated acceptable outcomes Expand in stages with named operational owners and continued monitoring

Do not choose pilot merely because the overall score appears acceptable. Do not choose scale because the technology performed well in isolation.

An unresolved difference of two or more points on a critical dimension prevents a scale decision until the evidence and scope have been reconciled.

Fix the blocker that matters to the first use case

A long transformation roadmap can dilute responsibility. Start with the constraint that most directly limits the first worthwhile use case.

Fix the blocker that matters to the first use case

Priority Meaning Response
Immediate blocker Critical to the use case, weakly evidenced and feasible to address Assign an owner, deadline and proof required before proceeding
Redesign trigger Critical but expensive, slow or structurally difficult to resolve Narrow, sequence or replace the use case
Capability investment Relevant across several use cases and likely to improve repeatability Fund as a shared organisational capability
Monitor Not currently critical or already well evidenced Retain an owner and define a review trigger

Avoid solving the easiest gap simply because progress will be visible.

If data rights are the constraint, an awareness course will not make the use case ready. If no one owns the workflow outcome, another technical demonstration may increase activity without resolving accountability.

Once a pilot has credible evidence, the challenge becomes operationalisation. LSI’s guide to moving AI from pilot to production examines that transition.

The cost of AI implementation also becomes clearer after the assessment has exposed integration, governance and adoption work that a software price omits.

Choose an assessment tool by what it can actually prove

AI readiness assessment tools are useful when they match the decision and make their limitations visible.

Before selecting one, ask what evidence it accepts, whether it distinguishes organisation-level and use-case readiness, how it treats critical gaps and whether recommendations can be traced to responses.

Tool type Useful for Main limitation
Online self-assessment Rapid orientation and a common vocabulary Often depends on respondent judgement and may conceal scoring logic
Workforce survey or template Comparing awareness and perceived barriers Perception does not prove operational or technical capacity
Facilitated internal workshop Investigating dependencies and agreeing ownership Hierarchy and group consensus can suppress disagreement
Independent evidence review Testing controls and delivery conditions Requires more time and access to operational material

Use a combination when the decision carries material cost or risk. A survey can identify a perception gap, a workshop can investigate it and evidence review can determine whether the claimed capability exists.

GenAI readiness requires additional evidence

A gen AI readiness assessment should retain the seven organisational dimensions while examining risks created or intensified by generative systems.

The NIST Generative AI Profile is a cross-sector companion to the AI RMF and can inform this additional work.

Add evidence questions covering:

  • the provenance, rights and permitted use of grounding and user-supplied content;
  • evaluation of factual reliability, harmful output and user needs;
  • prompt injection, sensitive-data disclosure and unsafe system connections;
  • changes to third-party models, service terms and data handling;
  • boundaries of human review where an output can trigger an action;
  • logging, incident investigation and feedback processes.

For agentic systems, assess the permissions attached to every action, not only the quality of generated text.

A system that can retrieve a document presents a different operational risk from one that can modify a record, contact a customer or initiate a transaction.

Readiness becomes credible when reassessment changes investment decisions

An AI readiness assessment expires as the organisation and use case change.

Readiness becomes credible when reassessment changes investment decisions

Reassess on a planned cycle and after material events such as a new data source, supplier change, workflow redesign, security incident or expansion to a different group of users.

Track whether the assessment changes decisions. Useful signals include unsuitable ideas being stopped earlier, evidence gaps receiving named owners, pilots having explicit exit criteria and scale funding being released only after operational proof.

If every assessment concludes that the organisation is ready, the method is probably confirming ambition rather than testing it.

The goal is not a perfect readiness score. It is a more defensible sequence of decisions about where AI can create value, what must be repaired first and what evidence is required before greater exposure.

These connections are examined in LSI’s MSc AI for Business Transformation through AI strategy and implementation, governance, change management and requirements engineering.

We value your privacy

London School of Innovation and its partners use cookies to enhance your browsing experience, ensure smooth service operation, provide personalised ads, and analyze traffic. By clicking "Accept All", you consent to our cookie use cookie policy.

Customise